

AI spend, governed like cloud.
Track LLM cost natively by model, team, product and feature, across every provider and every machine, without a single prompt leaving your tenant.
 and Mistral, Llama, Grok, DeepSeek, Copilot, self-hosted
What you get
Visibility down to the token.
All major LLMs
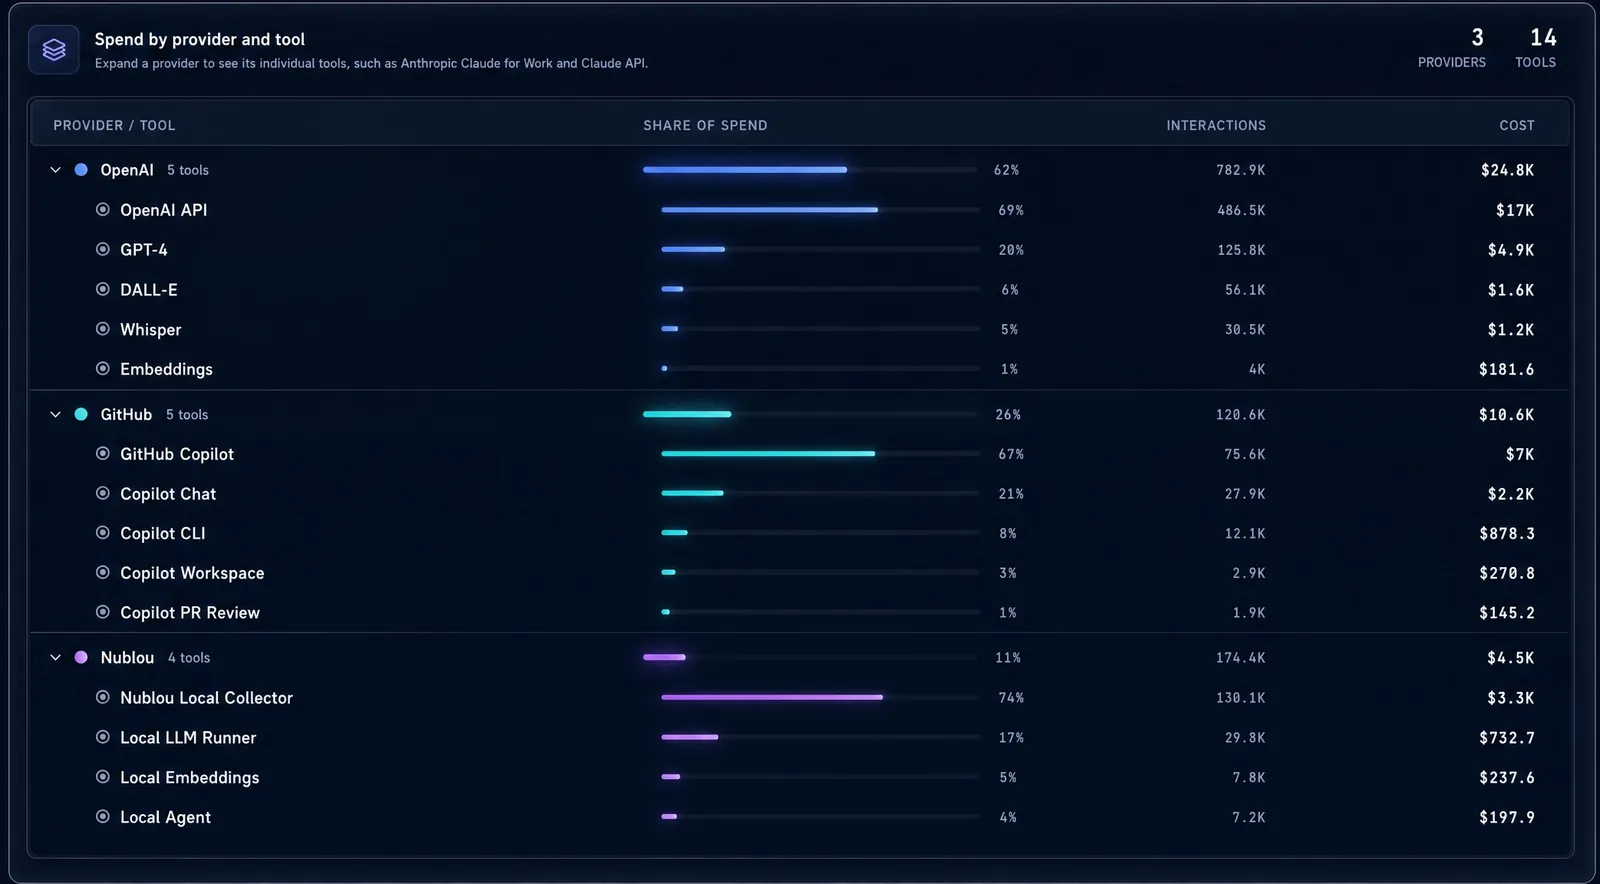
GPT, Claude, Gemini, Mistral, Llama, Grok, DeepSeek, OpenAI, GitHub Copilot, Ollama and self-hosted runners in one view.
Token-level granularity
Input and output tokens per API call, rolled up by team and product.
True AI unit economics
Cost per response, feature, segment and team.
Budgets and anomalies
Model-level budgets, proactive spend alerts and scheduled agents that watch for anomalies.
Provider comparison
Equivalent-workload benchmarking and provider swap analysis.
In-tenant privacy
API logs stay in your tenant. No prompts, completions or user data leave. Zero data egress.
The CFO question
The hidden AI bill, priced both ways.
Nublou prices the same usage at published API rates before the bill moves, so seat-to-token pricing never brings costs no one saw coming.
What you pay today
Subsidized plans
Flat seat pricing with usage hidden in provider dashboards. Heavy users look cheap.
What it could cost
Per-token API pricing
The same usage at published token rates, so the jump is a number you can plan for.
See it
Collectors capture usage wherever models run.
Forecast it
Team and product spend, quarter by quarter.
Compare it
In developmentLike-for-like on OpenRouter or Lightning.ai, or your own data centre with CapEx mapped to usage.
Local collector
See AI usage where it happens.
Usage aggregates, never prompts, flow into your Nublou tenant, including the user and department detail provider APIs leave out.
Where AI runsLaptops, servers and CI
Beside local models such as Ollama, GitHub Actions and agents.
Local collectorAggregate on device
Reads local usage metrics and sends only aggregates.
Your tenantOne central data store
Same Entra sign-in as the app. Feeds the UI, reports and MCP.